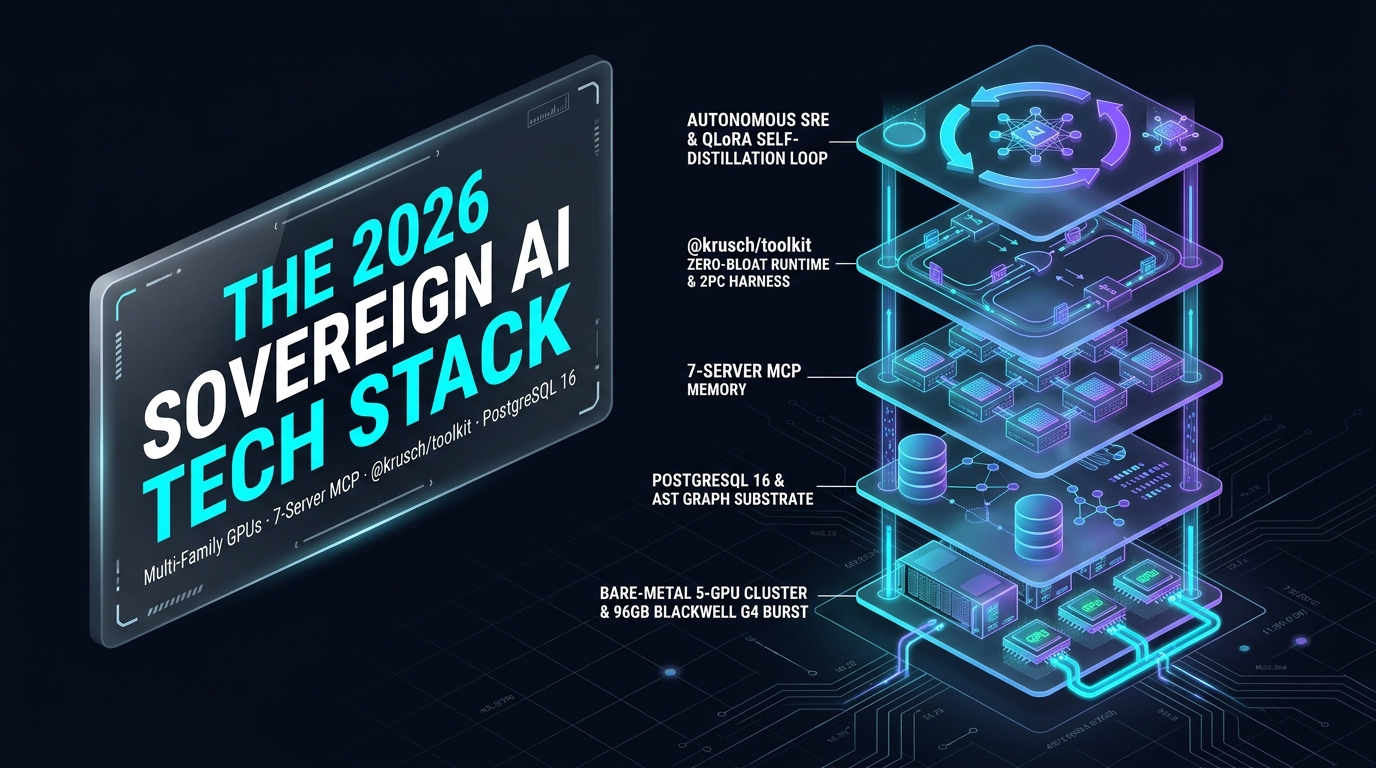
snowflake-arctic-embed2 vector plane, an 8-server Model Context Protocol (MCP) substrate backed by PostgreSQL 16 and SQLite WAL, a certified 39-brick dual-runtime substrate (@krusch/toolkit v1.8.1 & krusch_toolkit v1.6.0 enforcing 104/104 [100%] zero-boilerplate compliance across 16 <1ms Slop-Breaker detectors), Turn-0 grounded & import-frozen 2PC policy floors, and 24/7 autonomous SRE sweeps across 104 repositories that distill test-verified fixes into 4/4 open-weights QLoRA + DPO adapters—all packaged into a one-command installer (krusch-stack v1.1.0).
1. Why I Reject the Default 2026 AI Wrapper Stack
Across 35+ active core repositories and 104 audited software targets in my monorepo (104/104 [100%] zero-boilerplate compliance), one empirical rule dominates: probabilistic models fail predictably when forced to act as their own router, database, memory manager, policy engine, or code auditor.
Where conventional stacks paper over stochasticity with longer system prompts, my platform enforces hard systems boundaries:
- Multi-Family Model Isolation over Single-Vendor Monoculture: When a Qwen model writes code and another Qwen prompt reviews it, correlated pre-training blind spots slip into production. I isolate distinct model families across distinct physical GPU nodes so no model family ever grades its own homework.
- Microsecond CPU & Logprob Routing over LLM-as-Router Tax: Burning 500ms of frontier inference just to classify an intent is an architectural bug. My cascade router resolves deterministic patterns in
<15µsvia an in-process pure-CPU Stage-0 syntactic gate prior to model inference ($0.00), routes semantic queries via8KArctic centroids, and aborts degenerate streams live via SSE logprob gates—ranking top Pareto (0.4269,-83.95%cost) across12,566ACL 2026LLMRouterBenchprompts, #1 on MartianRouterBench(0.7488/0.7695ID &0.7268/0.7455OODAIQ), and scoring0.7263(#13 / 34,github-actions[bot]CI-verified upstream PR,RouteWorks/RouterArena PR #169open awaiting maintainer merge) across all8,400clean-room liveRouteWorks/RouterArenaqueries (74.44%Acc @$0.3802/1K,91.43%Robustness, beating MicrosoftAzure-Model-Router0.7037@$0.75/1K& OpenAIGPT-50.6432@$10.02/1K[26.4xcheaper]). - Relational Graphs & Multi-Scale Memory over Flat Chunks: Arbitrary 500-token chunking severs AST symbol scopes, statutory preemption DAGs, and PDF bounding boxes. I store Git DAGs, AST caller/callee edges, OS page trees, and hierarchical episodic rollups in PostgreSQL 16 +
pgvectorHNSW and SQLite WAL, indexed with 8,192-tokensnowflake-arctic-embed2asymmetric vectors. - Certified 39-Brick Toolkits, Turn-0 Grounded Harnesses & Import-Frozen Policy Floors: Every Node.js 22 ESM and Python 3.12 service assembles from
39certified dual-runtime Lego bricks in@krusch/toolkitv1.8.1(64.d.tssubpaths,141/141Node tests) &krusch_toolkitv1.6.0(201/201pytestsuites) plus7zero-LLM blueprints and16<1msSlop-Breaker detectors (krusch-lego,0/72scripts/), executes mutations behind Turn-0 grounded and2PCsandboxes, and ships via a single command (npx krusch-stack init --defer-tools).
┌─────────────────────────────────────────────────────────────────────────────────────┐
│                   THE 2026 KRUSCHDEV SOVEREIGN AI TECH STACK                        │
│   Unified Installer: `npx krusch-stack init --defer-tools` (v1.1) | `docker compose`│
├─────────────────────────────────────────────────────────────────────────────────────┤
│ PILLAR V   · AUTONOMOUS SRE & SELF-DISTILLATION (Jean SRE · 104 Targets · QLoRA+DPO)│
│              Argon + 120B Teacher ──(18,131 SFT+DPO)──► 4/4 31B/30B/120B/8B LoRAs   │
├─────────────────────────────────────────────────────────────────────────────────────┤
│ PILLAR IV  · HARNESS POLICY FLOORS, SPEC-FIRST & PARALLEL SUBAGENT ORCHESTRATION    │
│              Frozen spec.md ──► Disjoint Subagents ──► 3-Family Referee + 0-Turn    │
├─────────────────────────────────────────────────────────────────────────────────────┤
│ PILLAR III · 39-BRICK LEGO SUBSTRATE (@krusch/toolkit v1.8.1 · krusch_toolkit v1.6) │
│              64 .d.ts Subpaths · 7 Blueprints · 16 <1ms Slop-Breakers (104/104)     │
├─────────────────────────────────────────────────────────────────────────────────────┤
│ PILLAR II  · 8-SERVER MCP & 7-PILLAR STACK (`krusch-stack` · 39 Verbs / 9 BM25)     │
│              Tier 1: krusch-context v2.0 │ Tier 2A: krusch-git │ Tier 2B: krusch-fs │
│              Tier 3A: 2PC harness │ Tier 3B: grounded-harness v0.3 │ Domain MCPs    │
├─────────────────────────────────────────────────────────────────────────────────────┤
│ PILLAR I   · MULTI-FAMILY 5-GPU BARE-METAL + 8K ARCTIC + 96GB BLACKWELL G4 BURST    │
│              L0 (<15µs pure-CPU Stage-0) ─► L1/L2 5-GPU Pool (57GB+ VRAM · 10GbE)   │
│              ──► L2.5 Blackwell G4 (gpt-oss:120b / gemma4:31b) ──► L3 (Gemini Argon)│
└─────────────────────────────────────────────────────────────────────────────────────┘
2. Pillar I: Multi-Family 5-GPU Local Compute + 96GB Blackwell G4 Burst Topology
My compute plane operates as a 5-tier latency and capability cascade across an 8-node bare-metal Linux cluster interconnected over a dedicated 10GbE fabric, an ephemeral SSH cloud GPU burst tunnel, and frontier multimodal escalation.
A. The Bare-Metal 5-GPU Local Pool (100% GPU-Resident, keep_alive: -1)
Every local model is pinned 100% in VRAM with keep_alive: -1, q8_0 quantized KV caches, and zero-CPU-spill guards—eliminating cold-start reload thrash across interactive coding sessions and 24/7 background daemons:
| Compute Tier / Node Role | Hardware Profile | Pinned Models & KV Geometry | Architectural Responsibilities |
|---|---|---|---|
| Node-02 · Heavy Compute Host 10GbE Compute Plane |
Dual Xeon 40T · 64GB ECC Dual RTX 2080 Ti (22.5GB NVLink) |
qwen3-coder-30b-moe:latest( 16,384 ctx · q8_0 KV · 124.2 tok/s) |
Primary local code synthesis, multi-file AST refactoring, and 24/7 Jean SRE autonomous persona & lego_scout sweeps across 104 targets. |
| Node-01 · State & Referee Host 10GbE Production Plane |
Dual Xeon 40T · 80GB RAM Dual RTX 3060 (24.5GB VRAM) + Dedicated NVMe DB Array |
gemma4:e4b (16K ctx · native tools/thinking/vision/audio)hermes3:latest (16K ctx · q8_0 KV)snowflake-arctic-embed2:latest (8K ctx · 1,024-dim) |
Cross-Family Referee Pool (auditing Qwen outputs), SRE tool executor, statutory/contract prose, secondary embedding pool, and primary PostgreSQL 16 + pgvector HNSW host. |
| Node-03 · Orchestrator Host Central Control Plane |
i7-5820K · 32GB RAM RTX 2080 Ti (11.2GB VRAM) |
snowflake-arctic-embed2:latest (8,192 ctx · 1,024-dim · 664MB VRAM)qwen2.5-coder:7b (16K ctx · 74.6 tok/s)faster-whisper (base.en 16kHz ASR) |
Fleet-wide 8K-context asymmetric (query:) semantic embedding engine (89.17% Macro Recall@1 vs. 82.79% legacy 512-ctx bge-large across 119K+ active vectors), sub-second tag router, local IDE coding, and real-time voice ASR. |
| 5 Specialized Edge Nodes Tailscale + LAN Mesh |
Surface Kiosk, Travel Workstation, Mobile Auditor, Sandbox Worker, Media/Backup & Staging Nodes | Zero-daemon SSH targets & lightweight SQLite/DBOS workers | Touch/voice companion & wall-hub dashboards, isolated sandbox verification, media processing, and encrypted off-node backups. |
| Tier L2.5 · On-Demand Cloud Burst SSH Loopback Tunnel |
48 vCPU · 176GB RAM NVIDIA RTX PRO 6000 Blackwell (96GB VRAM) |
gpt-oss:120b (131,072 ctx · ~117.7 tok/s · 4-bit MXFP4)gemma4:31b (30.7B dense Q4_K_M & krush420/gemma4-31b-sre-lora) |
Provisioned via CLI for 120B architectural audits, closed-system DolphinBench (57.33% [344/600 @ $0.00, highest open-weights score in self-run 28-run evaluation; 54.17% [325/600] uploaded stock submission UUID 288671ad queued on dolphinbench.ai] Wave-6 LoRA + Grounded · 56.67% Stock + Grounded) / DABstep (40.0%, 2x) / BEAM / Polyglot / CoIR / RepoBench-R / LegalBench-RAG benchmarks, and 4-Adapter QLoRA + BF16 Ref-Anchored DPO fine-tuning; auto-stopped to 0.00 CU/hr on session close. |
| Tier L3 · Frontier Escalation Multimodal & Deep Reasoning |
Managed Frontier API + CLI (gemini-api v0.4.3) |
gemini-4-argon (65,536 max output · thinkingLevel · CONTINUATION)gemini-3.8-flash |
L0 specification synthesis, DolphinBench 91.17% (547/600 @ $24.54, uploaded dolphinbench.ai submission UUID c047b063, queued awaiting leaderboard acceptance; exceeds current 70.67% published entry) & 90.67% (544/600 @ $30.54, 90.50% [181/200] highest Riley slice in self-run 28-run evaluation) with Grounded v0.3, Snap LoCoMo (90.26% / 95.77% recall), DABstep (90.0% @ $0.81) reasoning, 3-viewport headless Chrome visual UI auditing (375/768/1440px), and Golden Remediation teacher traces. |
B. Cross-Family Referee Consensus: Why No Model Grades Its Own Homework
When qwen3-coder-30b-moe on Node-02 proposes a patch or audit finding, verification never routes back to a Qwen model. Instead, @krusch/toolkit's runThreeFamilyRefereeAudit, runRefereeAuditPass, and evaluateRefereeConsensus dispatch the candidate diff and frozen specification to gemma4:e4b and hermes3:latest on Node-01 (or gemini-3.8-flash / gemini-4-argon + OpenRouter deepseek/deepseek-v3.2 / gpt-oss:120b for L0 refactors). Orthogonal pre-training corpora and tokenizer geometries break self-reinforcing hallucination loops before any diff reaches disk.
3. Pillar II: The 8-Server MCP Ecosystem, Grounded Harness & Deferred Tool Loading
Dumping 80+ sprawling MCP schemas into every turn bloats prompt prefixes and degrades tool selection. I partition my operational surface into 8 focused MCP servers—each enforcing compact verb contracts (350–450 tokens), explicit 4-boolean MCP annotations (readOnlyHint, destructiveHint, idempotentHint, openWorldHint), token-budget ceilings (limit_tokens), and space-isolated 8K snowflake-arctic-embed2 vectors:
| MCP Server | Tier / Domain | Verb Contract | Storage, Benchmarks & Key Invariants |
|---|---|---|---|
krusch-context-mcpv2.0.0 (82★) |
Tier 1 Working Memory & Invariants |
5 Verbs:retrieve, remember, revise, nudge, health |
node:sqlite WAL + Porter FTS5 + Two-Level Episode Rollups + 2-Hop Gram-Schmidt Residual Bridges (<5ms, 0 RPCs) + attribute-level epistemic grounding + PG16 dual-write. Validated closed-system across all 1,540/1,540 Snap LoCoMo (ACL 2024) Category 1–4 QA probes (10 multi-month conversations / 5,882 turns, unmodified 0o444 SovereignMemoryStore, $0.00 zero-LLM ingestion via local snowflake-arctic-embed2 1024d + Porter-FTS5 4-Way RRF, 5/5 zero-leakage gates: 90.26% [1,390/1,540] judged accuracy, 95.77% dia_id evidence recall, & 181.8 ms median retrieval on argon_matched [+19.86 pp > LivingBrain zero-LLM 70.4%]; 89.68% [1,381/1,540] at 4,465 mean tokens [6.73x compression] & 91.05% dia_id recall on argon_tight; LoCoMo Oracle@2 = 92.66% [1,427/1,540]) and across all 2,000/2,000 Official ICLR 2026 BEAM (100K–10M, ~178.34M tok) probes: 92.58% 100K & 93.00% 10M IE recall, zero E2E drop to 1M (72.86%), beating cloud past.dev on CR (4/4 splits) & 10M MSR. Enforces Turn-1 Hydration, INV-12 SHA-256 drift checks & INV-LEGO-01 pre-commit guards. |
krusch-gitv1.2.3 |
Tier 2A AST & Git DAG Substrate |
7 Verbs:search_symbols, dependency_graph, file_symbols, semantic_search, read_tree, read_blob, list_repos |
PostgreSQL 16 + pgvector HNSW + stemmed tsv GIN. Multi-language AST chunker (JS/TS/Py/Go/Rust/Java) with live cursor import-activity analysis (analyzeImportSymbolActivity), oversampled HNSW/GIN CTEs (252ms → 15.25ms across 54,456 symbols), and 2-hop graph bridging. Ranked #1 (56.40% 10-Task Macro NDCG@10, 73.88% Recall@10) across all 2,389,123 docs & 162,216 queries of ACL 2025 CoIR and 19.12% Macro Acc@1 (68.58% Acc@5) across 47,998 RepoBench-R queries—beating CodeBERT & UniXcoder. |
krusch-fs-mcpv0.3.1 |
Tier 2B 8-Node OS Page Memory |
6 Verbs:search, locate, page_tree, read_page, remember_on_page, sync |
SQLAlchemy SQLite WAL / Postgres + KruschNexus Library Mode. Indexes PDFs, DOCX, /etc/systemd, and /etc/fstab across 8 SSH nodes with compact 4,096-byte IEEE-754 float32 vector blobs (-19% DB footprint), Porter FTS5, SHA-256 PageMemory drift checks, and pre-write secret-leak shielding. |
krusch-harnessv0.1.0 |
Tier 3A Staged 2PC Execution |
7 Verbs:run, task_status, diff, apply_diff, explain, reject, abort |
PostgreSQL 16 state machine + Bubblewrap (bwrap) sandboxes (108/108 tests + 100/100 Golden DAG CI). Enforces import-frozen policy floors, truncation-poisoning breakers, verify-on-stop outer loops, and <32ms 2PC commit finalization (scoped to the PostgreSQL write-ahead apply journal + POSIX atomic renameSync/fsync + pre-commit SHA-256 drift check boundary, excluding sandboxed test execution). Validated across 225/225 Aider Polyglot (19.56% → 51.56% Pass@2, 2.64x), 500/500 BIRD-SQL Mini-Dev (26.00% → 40.20% EX, 100% valid SQL), and 1,046 ETH SpyLab AgentDojo v1.2.2 episodes (19.28% → 0.00% Targeted ASR, 0.00 pp benign utility loss). |
krusch-grounded-harnessv0.3 (v0.2.0–v0.3.0) |
Tier 3B Turn-0 Grounded & Defect-Only Gate |
7 Verbs:ground_workspace, resolve_scale_profile, grounded_session_start, grounded_intercept, grounded_outcome, grounded_verify_stop, grounded_summary |
node:sqlite WAL + Turn-0 delta deduplication + passive BLOCK_SPIN_LOOP memoization + scale-aware 0-turn defect-only stop verification (INV-GH-01..10 / INV-STACK-11, 68/68 Node & 13/13 Python tests). Validated across 120 clean-room adyen/DABstep episodes (42/42 upstream scorer.py parity, 0o444 frozen data: 90.0% [9/10: 100% easy, 85.7% hard] on Gemini 4 Argon @ $0.81, -74.5% cost vs. $2.64/$3.19 ungrounded & 2.54x faster, 5.1 turns, 0 extra stop nudges; 2x accuracy [40.0% vs. 20.0% @ $0.00] on Gemma 4 31B; 30.0% local Qwen3-30B-MoE @ $0.00) and 4,200 Official DolphinBench traces across 7 grounded runs (90.67% [544/600 @ $30.54, 90.50% (181/200) highest Riley slice in self-run 28-run evaluation] on Gemini 4 Argon (Low) + Grounded Harness v0.3 [+2.00 pp over Std., highest invoked judge accuracy in self-run evaluation 553/590 = 93.73%; +1.50 pp / +9 net tasks over Grounded v0.2 89.17% (535/600) @ $23.92; Argon Low Oracle@2 = 94.67% (568/600), Oracle@3 = 95.83% (575/600), Argon Oracle@4 = 96.83% (581/600)], 57.33% [344/600 @ $0.00, highest open-weights score in self-run 28-run evaluation; 54.17% (325/600) uploaded stock submission UUID 288671ad queued on dolphinbench.ai] on krush420/gemma4-31b-sre-lora & 56.67% [340/600] Stock Gemma 4 31B @ $0.00, 43.00% [258/600] local 30B Wave-4 [highest Qwen/MoE score in 28-run self-run evaluation] @ $0.00, & 81.50% Luna High @ $1.35 [1.57x faster]). |
krusch-gateway-mcp |
Domain RAG Legal, Contract & Compliance |
5 Verbs (<450 tok):ask_law, ask_biz, check_compliance, ingest, purge |
Unified stdio proxy routing across KruschLaw (0.00% False Support Rate [FSR] on labeled statutory/contract golden sets), KruschBiz (confirmed-edge contract graphs), KruschBizLaw ("The Join"), and KruschNexus (v0.2.6, 206/206 tests; 26.74% Macro F1 [k=1] · 25.81% F1 / 44.72% Recall [k=2] · 47.71% Recall [k=6] across all 6,889 LegalBench-RAG queries with local mxbai-rerank-large-v2, beating OpenAI text-embedding-3-large + Cohere Rerank Recall@64 on MAUD at k=2). |
krusch-frontend-mcp |
UI Design Canonical Web & Lego Primitives |
get_canonical_template, list_canonical_templates, query_design_rules, css_to_tailwind, etc. |
Serves bit-for-bit HTML, 13-point Stealie dead-bolt SVG, and release-gated Lego UI primitives (article-shell, site-header, cyber-grid, nav-back, lego-*) plus responsive breakpoint specs. |
g-krusch |
Workspace Hub Google Drive, Docs, Cal & Mail |
12 Verbs:search_drive_rag, write_drive_file, get_agent_steering, etc. |
SQLite FTS5 + 8K snowflake-arctic-embed2 asymmetric Drive RAG with two-stage Top-128 cross-encoder reranking, AES-256-GCM OAuth vault, and native server-side .gdoc, .gsheet, and .slides OpenXML synthesis. |
One-Command Distribution, BM25 Deferred Bridge, Turn-0 Grounded Harness & 2PC Action Harness: krusch-stack v1.1.0
To make all 7 pillars installable in under 30 seconds across Claude Code, Cursor, Windsurf, and Antigravity, krusch-stack (v1.1.0, 68/68 tests) ships both zero-Docker local SQLite mode and a pre-wired PostgreSQL 16 + pgvector container stack—equipped with an Okapi BM25 Deferred Tool Bridge (--defer-tools), the Turn-0 Grounded Harness (krusch-grounded-harness v0.3 · INV-GH-01..10 / INV-STACK-11), and the Generalized 2PC Tool-Action Harness (INV-STACK-10):
- Zero-Setup Local SQLite Mode (
npx krusch-stack init --defer-tools): Uses Node.js 22 built-innode:sqlite(.krusch-stack/stack.db) with zero external daemons, auto-merging IDE MCP configs (.mcp.json,.cursor/mcp.json, Windsurf, Antigravity) and.agent/AGENTS.md. - Okapi BM25 Deferred Tool Loading (
--defer-tools): Cuts initial MCP tool-schema bytes by 68.5%—exposing only 9 upfront tools (Tier-1 memory essentials pluskrusch_tool_search,krusch_tool_describe, andkrusch_tool_call) while keeping all 39 annotated tools across 7 pillars discoverable on demand; validated across all2,251official UC BerkeleyBFCL v3Live queries inside a 64-tool hub (59.88% → 66.28%Micro Acc,-80.67%schema tokens/turn). - Turn-0 Grounded & Scale-Aware Defect-Only Harness (
INV-GH-01..10/INV-STACK-11·grounded-harness v0.3): ExposesPOST /grounded-harness/*(68/68Node &13/13Python tests), pairing Turn-0 workspace/schema grounding and delta deduplication with passiveBLOCK_SPIN_LOOPmemoization and0-turn defect-only stop verification (0extra self-doubt stop nudges). Hits90.0%(9/10:100%easy,85.7%hard) onGemini 4 Argon@$0.81(-74.5%cost vs.$2.64/$3.19ungrounded &2.54xfaster,5.1turns) and2xaccuracy (40.0%vs.20.0%@$0.00) onGemma 4 31B(30.0%localQwen3-30B-MoE@$0.00) across120clean-roomadyen/DABstepepisodes, while on OfficialDolphinBenchreaching90.67%(544/600@$30.54,90.50%[181/200] highestRileyslice in self-run 28-run evaluation) onGemini 4 Argon (Low) + Grounded Harness v0.3(+2.00 ppoverStd., highest invoked judge accuracy in self-run evaluation553/590 = 93.73%,+1.50 pp/+9net tasks overGrounded v0.289.17%[535/600] @$23.92,Argon Low Oracle@2 = 94.67%[568/600]), liftingkrush420/gemma4-31b-sre-lora(Wave-6 QLoRA+DPO) to57.33%(344/600@$0.00, highest open-weights score in self-run 28-run evaluation;54.17%[325/600] uploaded stock submissionUUID 288671adqueued ondolphinbench.ai;+3.17 pp/+19tasks over Stock &+0.67 ppover56.67%[340/600] StockGemma 4 31B + Grounded[+2.50 ppoverall /+5.50 ppRiley,15spin loops blocked]), lifting local30B Wave-4to43.00%(258/600, highest Qwen/MoE score in 28-run self-run evaluation @$0.00), and accelerating model-matchedGPT 5.6 Luna (High)1.57x(47.02s → 30.03s,81.50%[489/600] @$1.35). - Generalized
2PCTool-Action Harness (INV-STACK-10·action-harness-engine.js): ExposesPOST /action-harness/{start,intercept,outcome,verify-stop,summary}while preservingALL_STACK_TOOLS.length === 39(68/68Node &6/6Python tests)—eliminating-95.2%of duplicate MCP calls (42 → 2), cutting premature zero-action stops-50.0%, shrinking archive bloat-17.7%, liftingLBF>=4synthesis+6.67 pp(22.67% → 29.33%), and reaching50.33%(302/600)Oracle@2across all600OfficialDolphinBenchtasks on localQwen3-Coder-30B-A3B(Wave-4 QLoRA+DPO) at$0.00(plus10 → 0duplicate calls /+20.0 pp[0/10 → 2/10] recovery on the 10-task failure slice). - One-Command Docker Stack (
docker compose up -d): Bootspgvector/pgvector:pg16with all 9 relational/HNSW tables pre-initialized alongside the HTTP & MCP gateway on port3780.
# Option A: Zero-Docker local install + BM25 deferred tool loading (-68.5% schema bytes)
npx krusch-stack init --profile full --defer-tools
npx krusch-stack doctor

# Option B: Full PostgreSQL 16 + pgvector + HTTP/MCP Gateway container stack
git clone https://github.com/kruschdev/krusch-stack.git
cd krusch-stack && docker compose up -d
curl http://127.0.0.1:3780/health
4. Pillar III: @krusch/toolkit v1.8.1 & krusch_toolkit v1.6.0 — 39 Release-Gated Lego Bricks, 8K Embeddings & Raw-RAG
Every service in my monorepo—from voice kiosks and priority boards to statutory graph engines and CI healers—assembles from a certified, zero-boilerplate runtime enforcing 104/104 (100%, 0/72 scripts/) workspace compliance:
- 39 Dual-Runtime JS/TS & Python Lego Bricks (
@krusch/toolkitv1.8.1&krusch_toolkitv1.6.0): Ships64.d.tssubpaths backed by141/141Node.js 22 ESM (node:sqliteDatabaseSyncWAL +PRAGMA quick_checkself-healing,node --test,oxlint, React/Vite, Cloudflare Workers) and201/201Python 3.12pytestsuites (FastAPI,SQLAlchemy 2.0,Pydantic v2,PyArrow, Poppler TSV)—adding atomic409/422Idempotency-Keylocks (idempotency), immutable SHA-256/SQLite hash-chained ledgers (audit-log), zero-node:*RBAC/IDOR guards (rbac), and HMAC keyset cursors (pagination). - 7 Zero-LLM Blueprints & 16
<1msSlop-Breaker Detectors (krusch-lego): Stamps production project shells deterministically (krusch-lego stamp <archetype> <dir>) and runs16sub-millisecond AST/regex Slop-Breaker detectors (auditBoilerplateText,scoreLegoBrickCoverage—including unclamped Prisma/Mongoose pagination, outbound SSRF taint, and hardcoded auth-secret fallback detectors) inside MCP pre-commit gates—holding all104/104(100%,0/72scripts/) homelab repositories at zero reinvented boilerplate (Architecture Paper →). - Source-Preserving
Raw-RAGBaseline Discipline (arXiv:2610.30755): Before introducing lossy LLM memory summarization, services default to zero-LLM256/32-token phase-isolated sliding windows withTop-128 → Top-15cross-encoder / System-1 logprob reranking, graceful5,000-token turn-expansion fallback, and strict append-only (ADD/NONE) writes.
Inside @krusch/toolkit v1.8.1 & krusch_toolkit v1.6.0: 39 Certified Bricks Across 104/104 Repositories
import { decide } from '@krusch/toolkit/decide';
import { embedBatch, calibrateQuerySimilarity } from '@krusch/toolkit/embeddings';
import { createRawRagIndex } from '@krusch/toolkit/raw-rag';
import { auditPageWithArgon } from '@krusch/toolkit/browser';
import { runThreeFamilyRefereeAudit, evaluateRefereeConsensus } from '@krusch/toolkit';

// 1. Sub-millisecond cached / single-token logprob System-1 routing
const tier = await decide({
  prompt: 'Classify patch blast radius for AST symbol change in ast-chunker.js',
  choices: ['L1_FAST', 'L2_LOCAL_30B', 'L2_5_BURST_120B', 'L3_ARGON'],
  defaultChoice: 'L2_LOCAL_30B'
});

// 2. Sovereign 8K snowflake-arctic-embed2 batching + isotropic InfoNCE calibration
const vectors = await embedBatch(chunks, { model: 'snowflake-arctic-embed2', role: 'document' });
const calibratedScore = calibrateQuerySimilarity(rawCosine, 'snowflake-arctic-embed2');

// 3. Zero-LLM 256/32-tok Raw-RAG windowing + Top-128 -> Top-15 reranking
const rag = createRawRagIndex({ windowTokens: 256, overlapTokens: 32, candidateTopK: 128, finalTopK: 15 });

// 4. 3-Family Referee consensus + 3-viewport (375/768/1440px) Chrome Argon UI audit
const consensus = evaluateRefereeConsensus(await runThreeFamilyRefereeAudit({
  specMarkdown, candidateDiff, generatorFamily: 'qwen3', refereeModels: ['gemma4:e4b', 'hermes3:latest']
}));
const uiAudit = await auditPageWithArgon({ url: 'http://localhost:4080', viewports: [375, 768, 1440] });
| Toolkit Subpath | Key Exported Primitives | Engineering Problem Solved |
|---|---|---|
@krusch/toolkit/idempotency,./audit-log, ./rbac, ./pagination |
withIdempotency, createAuditLog, verifyAuditChain, createRbacPolicy, evaluateAccess, encodeCursor |
Atomic 409/422 Idempotency-Key mutation locks, immutable SHA-256/SQLite hash-chained audit ledgers, zero-node:* RBAC/IDOR ownership guards, and HMAC-signed keyset cursors. |
@krusch/toolkit/catalog,./scaffold & ./lego-scout |
listLegoBricks, auditBoilerplateText, scoreLegoBrickCoverage, scaffoldProject |
39-brick .d.ts catalog (64 subpaths), 7 zero-LLM blueprints, Rule-of-3 scouting, and 16 <1ms Slop-Breaker detectors enforcing 104/104 (100%, 0/72 scripts/) workspace compliance. |
@krusch/toolkit/embeddings &krusch_toolkit.embeddings |
embed, embedBatch, formatEmbeddingInput, calibrateQuerySimilarity |
Batched /api/embed client for 8K snowflake-arctic-embed2 (1,024-dim), MRL slicing, asymmetric query: prefixes, isotropic InfoNCE cosine calibration, and space-isolated LRU caches. |
@krusch/toolkit/raw-rag &krusch_toolkit.raw_rag |
createRawRagIndex, chunkConversationWindows, rerankCandidateWindows, auditRagBaselineConfig |
Zero-LLM 256/32-tok source-preserving RAG (Top-128 → Top-15 rerank, 5k turn expansion, ADD/NONE writes; arXiv:2610.30755) powering Companion, Agentic Proxy, G-Krusch & CI Sentinel. |
@krusch/toolkit/harness-engineering &./grounded-harness |
createFrozenPolicyFloor, createDeferredToolBridge, resolveScaleProfile, inspectOutputDefects |
Implements arXiv:2609.00006 & INV-GH-01..10: shell deobfuscation, parse-time policy floors, BM25 tool deferral, <UNTRUSTED_CONTENT> isolation, and scale-aware 0-turn defect-only stop gates. |
@krusch/toolkit/llm, ./vision,./browser & ./decide |
chat, callGeminiMediaJson, auditPageWithArgon, decide, selectCascadeTier |
Unified Ollama / OpenRouter / Gemini 4 Argon client (thinkingLevel, 65,536 output tok), 375/768/1440px Puppeteer visual UI auditing, and <25µs in-process pure-CPU Stage-0 syntactic cascade gating (prior to model inference) + single-token logprob routing. |
@krusch/toolkit(Referee, Context & KV/GVA) |
runThreeFamilyRefereeAudit, evaluateRefereeConsensus, createContextPruner, createKvCacheManager |
3-Family Referee convergence, 3-stage context pruning, SHA-256 artifact drift invalidation, trajectory loop breakers, and multi-GPU KV/GVA cache sizing. |
5. Pillar IV: Spec-First Engineering, Policy Floors & Disjoint Parallel Subagent Fan-Out
Whenever a build or refactor touches 3 or more independent modules (or mutates a database schema), the orchestrator enforces my L0 Spec-First & Disjoint Parallel Subagent Protocol (INV-606) combined with non-bypassable harness guards:
- Turn-1 Zero-Trust Hydration & Blast Radius Check: Hydrate active invariants via
krusch_context_retrieveand inspect inbound callers and outbound callees viakrusch_git_dependency_graphbefore editing a line of code. - Freeze Contracts in
spec.md: Lock exact function signatures, SQLite/PostgreSQL schemas, and JSON return shapes ({ ok, tool, summary, data }) inspec.mdprior to implementation. - Disjoint Subagent Fan-Out (
STRICT BOUNDARY RULE): Dispatch parallel subagents owning 1–2 disjoint files each. Subagents run localnode --check,npx oxlint, orpytestchecks behind an import-frozen policy floor and never touch shared choke points. - Choke-Point Wiring, Verify-on-Stop & 3-Family Referee Convergence: The parent orchestrator wires shared entrypoints (
src/server.js,src/agent/tools.js,client/src/App.jsx), blocks premature completion via the verify-on-stop loop until full hermetic suites pass, and clearskrusch_context_nudge({ trigger: "pre_commit" })+ 3-Family Referee consensus.
6. Pillar V: Closed-Loop Autonomous SRE & 4-Adapter QLoRA + DPO Self-Distillation
The crowning loop of the stack is that my infrastructure continuously audits, heals, and trains itself. On Node-02, my 24/7 daemon (Jean SRE) sweeps all 104 software targets across 11 code-audit checkpoints, 16 krusch-lego Slop-Breaker detectors (104/104 [100%] compliance, 0/72 scripts/), and 21+ infrastructure health gates—automatically reconciling resolved findings to maintain zero stale zombie blockers across the fleet.
A. Hermetic Verification & Portable Zero-Leak SFT + DPO Curation
Each sweep builds a fresh AST symbol graph, loads language-specific rules, runs Phase 1.9 Adversarial Steel-Manning plus Cross-Family Referee audits, and tests staged fixes inside isolated containers (node --test and pytest). Every remediation that passes 100% of unit tests with zero lint warnings is scrubbed by normalizePortableSftText—stripping private paths, IPs, and hostnames into portable $WORKSPACE_ROOT coordinates—and published to my 18,131-example SFT + DPO dataset across 7 splits on Hugging Face (krush420/sovereign-code-audit-sft: 15,290 11-phase Code Audit trajectories, 2,208 Elitist 120B Teacher rows, 401 Argon Golden Remediations, 150 Release-Gated Lego Brick SFT + DPO pairs, and 82 Agentic Memory Tool-Calling SFT + DPO pairs).
B. 4/4 Open-Weights QLoRA + BF16 Ref-Anchored DPO Fine-Tuning (31B Flagship, 120B Teacher, 30B Student & 8B Edge Referee)
Rather than letting frontier cloud escalations remain a sunk operating cost, high-complexity Gemini 4 Argon Golden Remediations, rejection-sampled 120B traces (requiring >=3 exact file:line citations and zero hallucination flags), and reference-anchored DPO preference pairs feed a 4-Adapter QLoRA + DPO Distillation Pipeline achieving 4/4 positive Official DolphinBench lifts:
- Track 1 — 31B Dense Open-Weights Flagship Wave-6 QLoRA+DPO (
krush420/gemma4-31b-sre-lora): Assistant-masked QLoRA + BF16 reference-anchored DPO onGoogle Gemma 4 31Bpaired withkrusch-grounded-harnessreaches57.33%(344/600@$0.00, highest open-weights score in self-run 28-run evaluation;54.17%[325/600] uploaded stock submissionUUID 288671adqueued ondolphinbench.ai;Morgan149/200 = 74.5%,Alex103/200 = 51.5%,Riley92/200 = 46.0%; Mech61.22%, Sem63.67%,50.81smedian, SHA-256b7a26ef9…) (+3.17 pp/+19tasks over Stock [+5Morgan,+8Alex,+6Riley],+0.67 pp/+4tasks over56.67%[340/600] Stock + Grounded,+2.50 ppover54.83%[329/600] Wave-5,+3.67 ppover53.67%[322/600] Wave-4,+22.00 ppover matched-scaleQwen2.5-Coder-32B35.33%, andGemma 4 Oracle@6 = 71.83%[431/600], beating all8non-Lunacloud stacks up to$1,830.57). - Track 2 — 120B Elitist Teacher QLoRA+DPO (
krush420/gpt-oss-120b-sre-lora): Native BlackwellMxfp4Config(dequantize=False)keeps all 128 MoE routed layers frozen in hardware 4-bit MXFP4 (~60.8GBVRAM) while training BF16 attention LoRA adapters (r=16, alpha=32onq/k/v/o_proj) +trl.DPOTrainerinside a single 96GB G4 GPU—driving loss from7.448 → 1.737(64.89%token accuracy) and lifting OfficialDolphinBenchto39.50%(237/600@$0.00, vs.39.17%Stock). - Track 3 — 30B Local Workhorse Student QLoRA+DPO (
krush420/qwen3-coder-30b-sre-lora): Distilled from my 18,131-row SFT + DPO corpus—driving loss from0.731 → 0.214(93.36%token accuracy), reaching100%--no-toolsRelease-Gated Lego Brick recall, deploying back to Node-02's dual bare-metal GPUs at 124.2 tok/s, and hitting43.00%(258/600, highest Qwen/MoE score in my 28-run self-run evaluation @$0.00, SHA-256efc93d02…) withWave-4 + Groundedon OfficialDolphinBench(42.67%[256/600] Wave-4 Std.,38.50%[231/600] Wave-6 + Grounded3.3B-active MoE capacity control;Wave-4 Oracle@3 = 58.50%[351/600],30B Oracle@5 = 61.17%[367/600]). - Track 4 — 8B Edge Referee & Tool-Caller QLoRA+DPO (
krush420/llama3-hermes3-8b-sre-lora): CalibratesNousResearch/Hermes-3-Llama-3.1-8Bon multi-turn memory tool schemas and DPO abstention/completeness pairs—lifting Official 600-taskDolphinBenchaccuracy15.7x(1.17% → 18.33%[110/600] at$0.00).
7. Hermetic External Benchmark Scorecard & 2026 Stack Reference Matrix
Every core substrate in the KruschDev ecosystem is Evaluated across 335,000+ traces and 14 external benchmark suites (with published SHA-256 audit logs and 95 / 95 clean-room SHA-256 gates)—with zero cloud API calls during local open-weights inference, runtime JS Proxy & frozen 0o444 SQLite oracle-leakage traps, mandatory Exercism test un-skipping, and 49 SHA-256-pinned Hugging Face audit logs (48 raw JSON + 1 live github-actions[bot] CI-verified upstream PR receipt bundle for RouteWorks/RouterArena PR #169 across 64 files, 40 dolphinbench_600 rows; plus clean-room DABstep, Snap LoCoMo & Grounded v0.3 artifacts) alongside all 28 SHA-256-pinned official 600-task openai/gpt-5.6-sol DolphinBench archives (16,800 traces across 6 model families: 17 $0.00 open-weights + 11 frontier/model-matched runs; 8 validated .zips queued on dolphinbench.ai awaiting upstream maintainer queue processing + 20 clean-room controls = 28/28 validated) extending Paper #27—published at krush420/sovereign-g4-benchmarks and krush420/sovereign-router-arena (full cross-stack analysis in Paper #22):
| Public Benchmark | Evaluated Sovereign Subsystem | Scale & Grading Discipline | Evaluated Sovereign Result & External Comparison |
|---|---|---|---|
| Snap LoCoMo (ACL 2024) Multi-Month Conversational Memory |
SovereignMemoryStore (unmodified 0o444 SQLite · $0.00 zero-LLM ingest via local snowflake-arctic-embed2 1024d + Porter-FTS5 4-Way RRF) |
1,540 / 1,540 Category 1–4 QA probes across 10 multi-month conversations (5,882 turns) · 5/5 zero-leakage gates |
90.26% (1,390/1,540) judged accuracy, 95.77% dia_id evidence recall, & 181.8 ms median retrieval on argon_matched (+19.86 pp > LivingBrain zero-LLM 70.4%); 89.68% (1,381/1,540) at 4,465 mean tokens (6.73x compression) & 91.05% dia_id recall on argon_tight; LoCoMo Oracle@2 = 92.66% (1,427/1,540). |
| ICLR 2026 BEAM Long-Term Agent Memory |
krusch-context-mcp (v2.0.0) |
2,000 / 2,000 probes across 100K–10M (~178.34M tokens) on local node:sqlite |
92.58% 100K & 93.00% 10M IE recall; zero E2E drop from 100K to 1M (72.86%); beats cloud past.dev on Contradiction Resolution (4/4 splits) & 10M Multi-Session Reasoning. |
| Official DolphinBench Multi-Session Memory Agents |
SovereignMemoryStore ($0.00 0o444 SQLite) + Gemini 4 Argon, GPT 5.6 Luna, gemma4-31b-sre-lora, Gemma 4 31B & 4/4 QLoRA+DPO (31B / 30B / 120B / 8B) + INV-STACK-11 Grounded v0.2/v0.3 & INV-STACK-10 2PC |
28 official 600 / 600 runs (16,800 openai/gpt-5.6-sol traces, 6 model families: 17 $0.00 open-weights + 11 frontier/model-matched) · frozen 0o444 SQLite · official openai/gpt-5.6-sol judge (8 validated .zips queued on dolphinbench.ai awaiting upstream maintainer queue processing, Argon Low UUID c047b063-822c-49fb-8b36-27c3763d6ca7, Medium UUID 29389157-b01b-42b5-8193-17d9a496f580 & Gemma 4 31B Stock UUID 288671ad-afe0-40a3-93af-b834c9bbd306, + 20 clean-room Wave-4/5/6, Grounded v0.2/v0.3, model-matched, 2PC & scaling controls = 28/28 validated) |
91.17% (547/600 @ $24.54, uploaded dolphinbench.ai submission UUID c047b063, queued awaiting leaderboard acceptance; exceeds current 70.67% published entry; 35.38s) with Gemini 4 Argon (Low) and 90.67% (544/600 @ $30.54, 90.50% [181/200] highest Riley slice in self-run 28-run evaluation) with Gemini 4 Argon (Low) + Grounded Harness v0.3 (+2.00 pp over Std., highest invoked judge accuracy in self-run evaluation 553/590 = 93.73%; +1.50 pp / +9 net tasks over Grounded v0.2 89.17% [535/600] @ $23.92; Argon Low Oracle@2 = 94.67% [568/600], Argon Low Oracle@3 = 95.83% [575/600], Argon Oracle@4 = 96.83% [581/600]; 89.17% / 535/600 on Argon Medium @ $24.57; 78.00% @ $15.76 Turn-0 Briefing-Only) on the byte-identical 0o444 frozen $0.00 SovereignMemoryStore (+20.50 pp / +123 tasks above the current 70.67% published entry [Hermes + GPT 5.6 Luna + Mem0 @ $96.21] at 3.9x lower cost), with model-matched GPT 5.6 Luna (High) + Grounded reaching 81.50% (489/600, 30.03s = 1.57x faster than 81.33% [488/600] Base @ $1.35, +10.83 pp over published 70.67% Mem0 at 71.1x lower cost; Luna Low 76.67% @ $1.10, 87.4x cheaper; Luna Oracle@5 = 91.83% [551/600])—proving 52.0% of my +20.50 pp gain is pure $0.00 Zero-LLM Raw-RAG memory (and 48.0% / +9.83 pp is the Argon Low backbone, p = 5.96×10⁻⁹; Global Oracle@28 = 98.33% [590/600, <= 1.67% (10/600) zero-LLM Raw-RAG misses], $0.00 Open-Weights Oracle@17 = 83.17% [499/600, +12.50 pp > published 70.67% Mem0] & Gemma 4 Oracle@6 = 71.83% [431/600, +1.16 pp > published 70.67% Mem0]; 4.19x LBF=4+ multiplier; 2×2 Thinking × Search ΔΔ = +3.17 pp, p = 0.0320; Return on Memory [queued submission] →); plus 57.33% (344/600 @ $0.00, highest open-weights score in self-run 28-run evaluation; 54.17% [325/600] uploaded stock submission UUID 288671ad queued on dolphinbench.ai; Morgan 149, Alex 103, Riley 92) on krush420/gemma4-31b-sre-lora (Wave-6 QLoRA+DPO + Grounded: +3.17 pp / +19 tasks over Stock, +0.67 pp over 56.67% [340/600] Stock Google Gemma 4 31B + Grounded [+2.50 pp overall / +5.50 pp on Riley, 15 spin loops blocked], 54.83% Wave-5, 53.67% Wave-4, 52.00% No-Think, +22.00 pp over matched-scale Qwen2.5-Coder-32B 35.33%), 43.00% (258/600) on local krush420/qwen3-coder-30b-sre-lora (Wave-4 + Grounded, highest Qwen/MoE in self-run evaluation; 42.67% [256/600] Wave-4 Std.; 38.50% [231/600] Wave-6 + Grounded; 30B Oracle@5 = 61.17% [367/600]) at $0.00 (39.50% 120B Wave-4; 39.17% 120B Stock; 38.50% 80B Stock; 35.33% 32B Dense Stock; 34.50% Hermes-4-14B Stock; 18.33% 8B Wave-4 = 15.7x lift)—beating all 8 non-GPT-5.6-Luna commercial cloud baselines up to $1,830.57, while full-600 INV-STACK-10 2PC Action Harness cuts duplicate MCP calls -95.2% (42 → 2 on local 30B Wave-4, 50.33% Oracle@2; 10 → 0 on 10-task slice; Local AI Study →). |
| Adyen DABstep Tier 3B Multi-Step Data-Science Agents |
krusch-grounded-harness (v0.2.0 · INV-GH-01..10 / INV-STACK-11) |
120 clean-room episodes across 4 models × 3 arms · 42/42 upstream scorer.py parity · 0o444 frozen data (0 LLM judges) |
90.0% (9/10: 100% easy, 85.7% hard) on Gemini 4 Argon @ $0.81 (-74.5% cost vs. $2.64/$3.19 ungrounded & 2.54x faster [75.5s vs. 191.5s], 5.1 turns, 0 extra stop nudges) and 2x accuracy (40.0% vs. 20.0% @ $0.00) on Gemma 4 31B (30.0% local Qwen3-30B-MoE @ $0.00). |
| Martian RouterBench, RouterArena & ACL 2026 LLMRouterBench ID & OOD Multi-Model Routing |
krusch-pre-router + krusch-cascade-router + 8K Arctic |
72,980 Martian ID + Leave-1-Out OOD + 8,400 clean-room live RouteWorks/RouterArena PR #169 (+420 robustness, github-actions[bot] CI-verified upstream PR open awaiting maintainer merge) + 12,566 LLMRouterBench + 1,229 Live SSE + 240 Polyglot trajectories |
top Martian ID AIQ (0.7488 / 0.7695, -72.63% cost @ 98% GPT-4) & top OOD AIQ (0.7268 / 0.7455); 0.7263 (72.63, #13 / 34, github-actions[bot] CI-verified upstream PR, RouteWorks/RouterArena PR #169 open awaiting maintainer merge) on RouterArena (74.44% Acc @ $0.3802/1K, 91.43% Robustness, 0 abnormal, 8,400 live gen-... receipts, beating Microsoft Azure-Model-Router 0.7037 @ $0.75/1K, OpenAI GPT-5 0.6432 @ $10.02/1K [26.4x cheaper], Martian 0.5756 & NotDiamond 0.5729); #1 Lowest Pareto Distance (0.4269, -83.95% cost) on LLMRouterBench (25.25% vs 8.75% / 2.89x RouteLLM on OOD ARC-AGI); -48.0% TTFT live SSE cascade. |
| ETH SpyLab AgentDojo v1.2.2 Indirect Prompt-Injection Defense |
createKruschPolicyFloor + Capability/Taint Guard |
1,046 / 1,046 official episodes (97 benign + 949 ImportantInstructionsAttack across workspace, banking, slack & travel) |
Drives Targeted Attack Success Rate from 19.28% (183/949) & 14.86% Spotlighting → 0.00% ASR (0/949 across 1,046 episodes, 100% Defense) across all 4 suites while preserving 61.86% Benign Utility (0.00 pp loss, 83 blocks). |
| ACL 2025 CoIR & RepoBench-R Full-Corpus & Cross-File Code IR |
krusch-git (v1.2.3) + 8K Arctic + AST Hybrid RRF |
All 10 / 10 CoIR tasks (20/20 unshrunk corpora: 2,389,123 docs, 162,216 Qs) + 47,998 Py/Java RepoBench-R Qs |
#1 56.40% 10-Task Macro NDCG@10 & 73.88% Recall@10 on CoIR (+7.42 pp over BM25; +8.00 pp codefeedback-mt); 19.12% Macro Acc@1 (68.58% Acc@5) & 31.33% Py / 27.45% Java cfr Easy on RepoBench-R (beats CodeBERT & UniXcoder). |
| Aider Polyglot & BIRD-SQL Mini-Dev 2PC Code & Enterprise SQL Healing |
krusch-harness 2PC + Read-Only node:sqlite + gpt-oss:120b |
225 / 225 6-language Exercism tasks (skipped tests activated) + 500 / 500 dirty SQLite queries across 11 DBs |
Aider Polyglot: 19.56% → 51.56% Pass@2 (2.64x, +72 healed; ties Claude 3.5 Sonnet 51.6% & beats GPT-4o 23.1%). BIRD-SQL: 26.00% → 40.20% EX (1.55x, 35.75% R-VES, 100.00% valid SQL, 5.00x on toxicology). |
| UC Berkeley BFCL v3 Live Enterprise 64-Tool MCP Calling |
krusch-stack (v1.1.0) BM25 Deferred Bridge + Schema Guard |
All 6 / 6 official BFCL v3 Live splits (2,251 / 2,251 queries) mounted inside a 64-tool Enterprise MCP Hub |
Lifts Micro Accuracy from 59.88% → 66.28% (+144 Qs) and 6-Split Macro from 41.00% → 48.72% (84.69% Irrelevance abstention, +17.46 pp) while cutting schema tokens by -80.67% (7,894 → 1,526 tok/turn). |
| LegalBench-RAG Character-Exact Span RAG |
KruschNexus v0.2.6 + 8K Arctic + mxbai-rerank-large-v2 |
714 corpus docs · 6,889 full / 776 mini queries · sort_by_document: false · char-exact overlap |
26.74% Full Macro F1 (k=1, +82.8% over bi-encoder & 2.29x over fixed dense), 25.81% F1 / 44.72% Recall (k=2, retaining 93.7% of k=6 recall 47.71%; 0 FTS5 crashes), and 33.95% MAUD Recall@2—surpassing published OpenAI text-embedding-3-large + Cohere Rerank Recall@64 = 28.28%. |
Complete 2026 Architectural Reference Matrix
| Stack Layer | Primary Technologies & Projects | Key Metrics & Invariants |
|---|---|---|
| 0. Unified Distribution | krusch-stack (v1.1.0 · npx krusch-stack init --defer-tools / Docker Compose) & krusch-grounded-harness (v0.3) |
Bundles all 7 pillars, 39 annotated MCP tools, and 68/68 tests; Okapi BM25 --defer-tools cuts upfront schema bytes by 68.5% (39 → 9 tools) and schema tokens by -80.67% across 2,251 BFCL v3 Live queries (66.28% Micro Acc); INV-STACK-11 Turn-0 Grounded Harness hits 90.0% @ $0.81 (-74.5% cost, 2.54x faster) on adyen/DABstep, 2x (40.0% vs. 20.0% @ $0.00) on Gemma 4 31B, and 90.67% (544/600 @ $30.54, 90.50% [181/200] highest Riley slice in self-run 28-run evaluation) on DolphinBench; INV-STACK-10 2PC Action Harness cuts duplicate MCP calls -95.2% (42 → 2 across 600 tasks on local 30B Wave-4, 50.33% Oracle@2 @ $0.00; 10 → 0 & +20.0 pp on 10-task slice). |
| 1. Routing & Gating | krusch-pre-router, krusch-cascade-router, @krusch/toolkit/decide |
<15µs in-process pure-CPU Stage-0 syntactic gate prior to model inference ($0.00), #1 Martian RouterBench ID & OOD (0.7488 / 0.7695 ID, -72.63% cost @ 98% GPT-4; 0.7268 / 0.7455 OOD), 0.7263 (#13 / 34, github-actions[bot] CI-verified upstream PR, RouteWorks/RouterArena PR #169 open awaiting maintainer merge) clean-room live RouterArena (74.44% Acc @ $0.3802/1K, 91.43% Robustness, beating Azure-Model-Router 0.7037 & GPT-5 0.6432 [26.4x cheaper]), #1 ACL 2026 LLMRouterBench Pareto (0.4269, -83.95% cost), and -48.0% TTFT live SSE cascade (Interactive Arena →). |
| 2. Local GPU & Vector Pool | 5 Bare-Metal GPUs (57GB+ VRAM) over 10GbE · Ollama / vLLM (keep_alive: -1) |
qwen3-coder-30b-moe (124.2 tok/s), gemma4:e4b, hermes3:latest, qwen2.5-coder:7b (74.6 tok/s), snowflake-arctic-embed2 (8K ctx, 1,024-dim, 89.17% R@1). |
| 3. Cloud Burst & Frontier | 96GB RTX PRO 6000 Blackwell G4 + gemini-4-argon (gemini-api v0.4.3) |
gpt-oss:120b (~117.7 tok/s, 131K ctx) & gemma4:31b (auto-stopped 0.00 CU/hr) + Gemini 4 Argon 3-viewport Chrome visual UI auditor. |
| 4. 3-Tier Coding & Grounded MCPs | krusch-context-mcp (v2.0.0), krusch-git (v1.2.3), krusch-fs-mcp (v0.3.1), krusch-harness, krusch-grounded-harness (v0.3) |
90.26% Snap LoCoMo (1,390/1,540, 95.77% dia_id recall, 89.68% tight @ 6.73x compression, 92.66% Oracle@2 @ $0.00 ingest), 2,000/2,000 BEAM (93.00% 10M IE), 91.17% (547/600, Queued Upload UUID c047b063; > 70.67% published #1) on DolphinBench 600 across 28 runs / 16,800 traces (Argon Low @ $24.54; 90.67% [544/600 @ $30.54, 90.50% (181/200) highest Riley slice in self-run 28-run evaluation] Argon Low + Grounded v0.3; 94.67% Argon Low Oracle@2, 95.83% Oracle@3, 96.83% Argon Oracle@4; 81.50% model-matched GPT 5.6 Luna + Grounded @ $1.35, 30.03s = 1.57x faster & 71.1x cheaper; 57.33% [344/600 @ $0.00, highest open-weights score in self-run 28-run evaluation; 54.17% (325/600) uploaded stock submission UUID 288671ad queued on dolphinbench.ai; 56.67% Stock + Grounded] on krush420/gemma4-31b-sre-lora + Grounded & 43.00% local 30B Wave-4 + Grounded [42.67% Std.] @ $0.00; 98.33% Global Oracle@28 [590/600, <= 1.67% misses], 83.17% $0.00 Oracle@17 & 71.83% Gemma 4 Oracle@6), 90.0% adyen/DABstep @ $0.81, #1 56.40% ACL 2025 CoIR (2.39M docs) & 19.12% RepoBench-R, 51.56% Polyglot (2.64x), 40.20% BIRD-SQL (100% valid SQL), and 0.00% ASR across 1,046 AgentDojo v1.2.2 episodes. |
| 5. Release-Gated Lego Runtime & Raw-RAG | @krusch/toolkit (v1.8.1) & krusch_toolkit (v1.6.0) · Node.js 22 ESM, Python 3.12, React + Vite + Tailwind |
39 dual-runtime Lego bricks (64 .d.ts subpaths, 141/141 Node & 201/201 pytest suites, incl. atomic idempotency locks, SHA-256/SQLite audit-log, zero-node:* rbac/IDOR guards, HMAC keyset pagination, 256/32-tok raw-rag, & grounded-harness) + 7 zero-LLM blueprints + 16 <1ms Slop-Breaker detectors (krusch-lego) enforcing 104/104 (100%, 0/72 scripts/) zero-boilerplate compliance. |
| 6. State & Databases | PostgreSQL 16 + pgvector HNSW, SQLite WAL, @krusch/polygres-connector, DBOS |
Dedicated NVMe storage isolation (OS drives protected), <32ms 2PC commit finalization (PostgreSQL write-ahead apply journal + POSIX atomic renameSync/fsync + pre-commit SHA-256 drift check), automatic SQLite quick_check self-healing, and SHA-pinned Polygres sync. |
| 7. Domain Intelligence | KruschNexus, KruschLaw, KruschBiz, Authority Packs, krusch-gateway-mcp, g-krusch |
26.74% LegalBench-RAG Macro F1 (47.71% Recall across 6,889 Qs with mxbai-rerank-large-v2), 0.00% False Support Rate (FSR) on labeled statutory/contract golden sets, 100% citation accuracy & Drive OpenXML synthesis. |
| 8. Autonomous SRE & R&D | jean-sre (24/7 daemon), krusch-ci-sentinel, Blackwell MXFP4 QLoRA+DPO pipeline |
104/104 workspace targets swept (100% Lego compliance, 0/72 scripts/, 0 zombie blockers); 18,131 Zero-Leak SFT + DPO rows across 7 splits + 4/4 open-weights QLoRA+DPO adapters on Hugging Face: 31B (57.33% highest open-weights in 28-run self-run evaluation; 54.17% queued stock UUID 288671ad), 120B (39.50%), 30B (43.00% highest Qwen/MoE in self-run evaluation, 93.36% acc) & 8B (15.7x lift). |
Install the Unified KruschStack in 30 Seconds
npx krusch-stack init --defer-tools · v1.1.0 · MIT Licensed · Node 22 SQLite & Docker Compose · 39 Annotated MCP Tools · 39 Release-Gated Lego Bricks
